Resize a server in place
Add CPU or RAM to the servers of a service one server at a time, then retune the PostgreSQL settings of the service to the new size.
Shut down one server at a time, change its CPU or RAM, and power it on. On an HA service, the other members continue to serve. The resize includes one switchover.
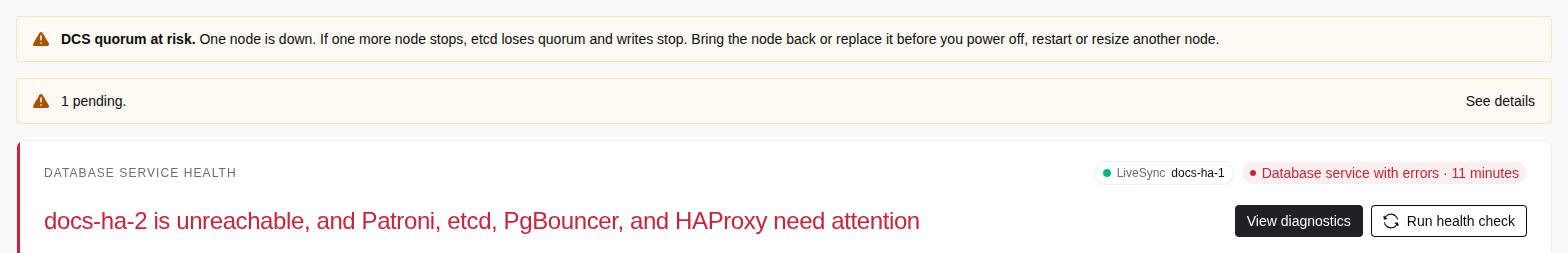
While one member is down, the service Overview shows the DCS quorum at risk banner. The console does not prevent a power-off. While the banner shows, do not power off, restart or resize another node.
Before you start
- The service Overview shows the service as healthy, and no operation runs. The topology shows one Primary, and each replica with a lag near zero.
- The Overview shows no DCS quorum at risk banner. On Advanced HA, the cluster on Infrastructure → DCS clusters is healthy.
- You have a recent backup.
If you cannot confirm a prerequisite, do not start.
HA service: rolling resize
Resize the replicas first. Then switch over to a resized replica, and resize the old primary last.
Shut down a replica
Connect to a replica, and shut it down cleanly:
sudo shutdown -h nowIf the node held the VIP, the VIP moves, and connections through it close once.
Resize the server
Wait for the server to power off. Change its CPU or RAM, then power it on.
Check that it rejoins
Wait until the topology shows the node as a healthy replica with a lag of zero, and the DCS quorum at risk banner is gone. If not, do not resize another node. Follow If a node does not join the cluster again.
Resize the other replicas
Do steps 1 to 3 for each other replica, one at a time.
Switch over
On the Overview topology, open the menu of a resized replica and select Switchover (see Failover and switchover). Connections through the VIP close once.
Check the new primary
Confirm that the topology shows the new primary, and the old primary as a healthy replica. If the switchover fails, or the old primary is not a healthy replica, do not shut it down. Contact support.
Resize the old primary
Do steps 1 to 3 on the old primary.
Switch back (optional)
Switch over to the node that you prefer, and check it as in step 6.
Advanced HA: resize DCS servers
Resize one DCS server at a time. All services that use the DCS cluster depend on its quorum.
Check the DCS cluster
On Infrastructure → DCS clusters, confirm that all three members are healthy.
Shut down the server
Connect to the DCS server, and shut it down with sudo shutdown -h now.
Resize the server
Wait for it to power off. Change its CPU or RAM, then power it on.
Check that it rejoins
Wait until the DCS cluster page shows the member and the cluster healthy. If it does not recover, do not shut down another server, and contact support.
Single-node service
The resize stops the service.
Stop the applications
Stop the client applications.
Shut down the server
Shut down the server with sudo shutdown -h now.
Resize the server
Wait for the server to power off. Change its CPU or RAM, then power it on.
Start the applications
Wait until the console shows the service as healthy. Then start the applications. If the service does not recover, contact support.
After the resize
The PostgreSQL settings do not change. To tune them to the new size, open Database service admin and select Retune under Operations. Retune uses the license size, or the server size if the server is smaller.
Retune restarts PostgreSQL: one switchover on an HA service, a short outage on a single node. Check the result on Operations. See Changing the license of a deployed service.
If a node does not join the cluster again
- HA PostgreSQL node: follow Node power loss, from step 4 of Recovery. A rebuild deletes the data directory of the member.
- Single node or DCS server: contact support.
If two etcd members are off, power on one of them. If the cluster does not recover, see Site outage and recovery.