Backups found corrupt pages
A backup found invalid page checksums. Find the corrupt files, get a clean copy of the data from a replica or a backup, and check the result.
Cause
A backup found pages with an invalid checksum. The cause is usually a fault in the disk, the storage controller, the file system or the memory of a server. The backup completes with the corrupt pages. The corrupt file is on the server that the backup copied from. On an HA service, that can be a replica.
Symptoms
-
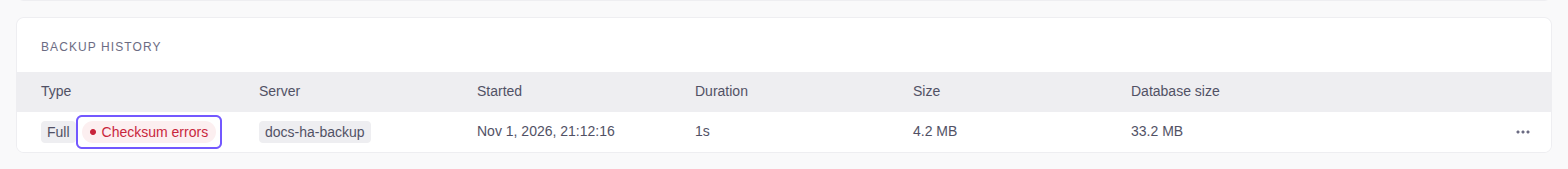
In Backup history on the Backups tab, a backup has the mark Checksum errors.
-
The Overview shows Backups need attention. The Backups health shows Backup
<label>found invalid page checksums: some data files are corrupt. -
After 15 minutes, the alert
BackupNeedsAttentionfires. -
The backup log has one line for each corrupt page:
P00 WARN: invalid page checksum found in file <data_dir>/base/5/16384 at page 0 -
Queries that read a corrupt page fail with
ERROR: invalid page in block 0 of relation base/5/16384. -
A backup that you start in the console completes with the warning Backup completed. Old backups and WAL were not removed. Old backups and WAL stay on the disk until the marked backup leaves retention.
Backup and restore behavior
A restore stops at the first file with invalid page checksums. PostgreSQL then cannot start from the data directory.
The console refuses a restore in place, a recover and a fork that land on a backup with the mark, or on a differential or incremental backup that depends on one:
- A backup: the restore pickers show it as not available. Restore this database service and Restore to a new database service are not available on its row.
- Latest: when the newest backup has the mark, the restore card starts on the newest backup without the mark.
- Point in time: when the backup before the time has the mark, pick an earlier time.
When no clean backup exists, an admin can force a restore through the API to
get the pages that are not corrupt. An in-place restore replaces the service
data. The audit log records the override. API operation:
POST /api/v1/database-services/{id}/restore (admin) with
{"mode": "immediate", "backup_set": "<label>", "allow_checksum_errors": true}
(see the API reference). A forced restore also stops at the
first corrupt file. A forced fork fails at once: remove the new service.
Find the corrupt files
The console does not show which files are corrupt, or which copy is clean. Use these commands.
List the corrupt files
List the corrupt files. Run this on the server that holds the backup repository: the database server for a local copy, the backup server for a remote copy. The stanza is the name of the service, unless you set another stanza.
sudo -u postgres pgbackrest --stanza=<stanza> info --set=<label>The output ends with the files, relative to the data directory:
error list: base/5/16384The page numbers are in the backup log: the Output of its operation
for a backup that the console started, or
/var/log/pgbackrest/<stanza>-backup.log on the server that ran the
backup. If you cannot find the server that the backup copied from, check
every copy.
Find the table or index
Find the table or index. In base/<database oid>/<file node>, a suffix
.1, .2 is the next 1 GB part of the file. A suffix _fsm or _vm is
the free space map or visibility map of the table. On any running server,
get the database name (replace 5 with the database OID):
SELECT datname FROM pg_database WHERE oid = 5;Connect to that database. Get the table or index (replace 16384 with the
file node, without a suffix):
SELECT pg_filenode_relation(0, 16384);Check each replica
On an HA service, check each replica, one at a time. Do not stop the primary. Confirm that the server is a replica and that the service can run without it. Then stop Patroni and read the state:
sudo systemctl stop patroni
sudo -u postgres /usr/lib/postgresql/<version>/bin/pg_controldata <data_dir> | grep "Database cluster state"
Good: shut down in recovery. If it is in archive recovery, PostgreSQL
is still running. Confirm again that the server is a replica, then stop
PostgreSQL and read the state again:
sudo -u postgres /usr/lib/postgresql/<version>/bin/pg_ctl -D <data_dir> stop -m fastIf the state is still not shut down in recovery, do not run
pg_checksums. Start Patroni and contact Tiger Data support. Else check
all pages and start Patroni:
sudo -u postgres /usr/lib/postgresql/<version>/bin/pg_checksums --check -D <data_dir>
sudo systemctl start patroni
Good: Bad checksums: 0. Any other result: this copy is not clean. Start
Patroni in all cases. Wait until the replica streams again before you
check the next one.
Check the primary
On the writable primary, check tables and indexes while PostgreSQL runs.
--install-missing creates the extension amcheck in each database:
sudo -u postgres /usr/lib/postgresql/<version>/bin/pg_amcheck --all --install-missingOn a read-only replica, amcheck must already be in the databases. Then
run the command without --install-missing.
Bad checksums: 0 and a clean pg_amcheck do not prove that there is no
other corruption.
Recovery
The file is an index
Connect to the database of the index. Rebuild the index (use the schema-qualified name). The new index does not use the corrupt file:
REINDEX INDEX CONCURRENTLY <index>;A replica has corrupt files
Check the primary copy
Make sure that the primary has a clean copy (see Find the corrupt files). If not, use the steps for the primary or for no clean copy below.
Rebuild the replica
Rebuild the replica from the primary with the API:
POST /api/v1/database-services/{id}/servers/{server_id}/rebuild-replica
(admin). The console refuses the primary, and needs every other server
healthy. See the API reference.
Wait for streaming
Wait until the replica streams again.
The primary has corrupt files (HA)
Check a replica
Check a replica with pg_checksums (see
Find the corrupt files). If it is not clean,
check another replica, or use the steps for no clean copy.
Switch over
When the checked replica streams again, open the Overview of the service. Open the menu of that replica and select Switchover. Writes stop during the switchover. See Failover and switchover.
Check the new roles
Make sure that the checked replica is the primary and the old primary is a replica. If the switchover failed, stop.
Rebuild the old primary
Rebuild the old primary as in A replica has corrupt files.
No clean copy (single server, or every replica has the fault)
Find a clean backup
In Backup history, find a backup with no Checksum errors mark.
Restore to a new service
Open its menu and select Restore to a new database service. See Restore into a new service. With a later restore point, archived WAL replays up to that point.
Check the new service
Check the new service with pg_amcheck and validate the data.
Move the clients
Move the clients to the new service only when the checks pass.
After the recovery
Open the Backups tab
On the recovered service (the new service after a restore), open the Backups tab.
Take a full backup
Select Trigger backup, then Full backup.
Check the new backup
Check that the new backup has no Checksum errors mark. If it does, the recovery is not complete.
Older backups keep the mark until retention removes them.
Find the cause: check the disk (smartctl), the kernel log
(journalctl -k) and the memory of the server.