Manage servers
Test, rename, re-enroll, clean up and delete servers, find the cause of Needs cleanup, and grow the storage of a server in use.
Infrastructure → Servers lists the servers.
| Usage | Meaning |
|---|---|
| Free | Nothing uses the server. It can fill a member slot or serve a new service. |
| In use | A database service, a DCS cluster, a backup repository or a LiveSync session uses the server. The column names each use, for example svc-a · pgnode02 or svc-a · backups. |
| Needs cleanup | The cleanup failed or could not run. See Needs cleanup. |
| Health | Meaning |
|---|---|
| Healthy | The console reaches the server, and each check passed. |
| Warning or Error | A component needs attention, for example Patroni or PgBouncer. Error also shows when the console could not check the server for more than 15 minutes. |
| Unreachable | The console cannot reach the server over the mesh. |
| Unknown | The console cannot reach the mesh, or has no recent reading. |
| No reading | The console did not check the server yet. |
Hover over the health to see the reason and since when. The console checks each server once a minute. The refresh button checks each server now.
Actions:
- Test server (server menu, operator or admin): runs an SSH connection check now.
- Re-enroll command (server menu, admin): makes a new enroll command and cancels the previous one. Use it after an OS reinstall or a change of the console address. After a reinstall, rebuild the member (see Rebuild after a reinstall).
- Replace server (node menu on the service Overview or on a DCS cluster): see Replace a server.
- Retry cleanup (admin): see Needs cleanup.
- To rename a server, use
PATCH /api/v1/servers/{id}with{"name": "<new name>"}(admin). The console has no control for it.
Infrastructure → Mesh shows the mesh Status of the console and each server: Online, Unreachable or Unknown. Last handshake renews about every 2 minutes while the link is in use, so an age of a few minutes does not mean that the server is down.
The server page
Select a server to open its page. Under the name, one callout lists the problems of the server, for example Reboot required, Restart pending or Versions differ. Each line says what to do, and links to the control when the console has one. You reboot the server yourself.
- Summary: the roles, the hardware, the OS, the versions, the data disk use and the mesh path (Direct or Relayed). Test server tests the SSH connection.
- Software: the pack release, a pending reboot or restart, and the installed components. Select Components to see their versions.
- Patroni: the role, the state, the replication lag and the timeline of the Patroni member.
- Network: the mesh enrollment and the client interface, the address that database clients connect to.
- Storage: the disks, the data disk first.
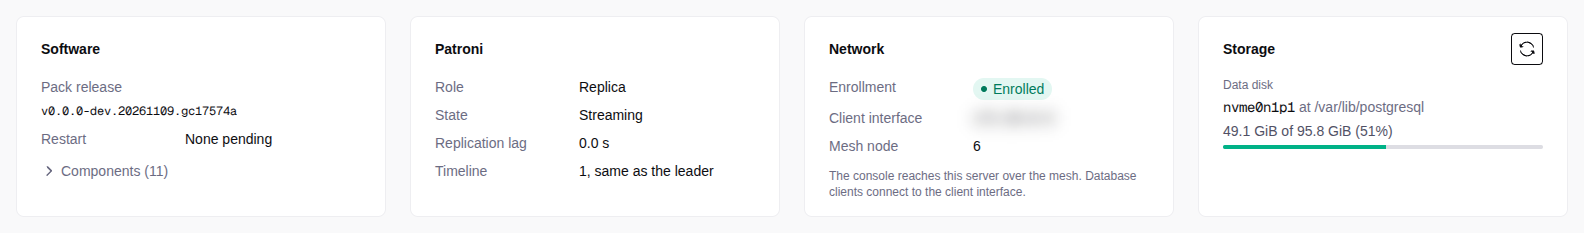
A new server shows more values after its first deploy.
Server cleanup
When a server leaves its last role, the console cleans it up at the end of that operation. A server that keeps another role loses only the software of the role that left.
The cleanup deletes the PostgreSQL and etcd data directories on the server.
On a custom data directory, it deletes only <data directory>/<major>. It
also removes the database software, its services, configuration, logs and
users, the package sources of the console, and the OS settings of the deploy.
The server keeps its mesh enrollment, the tse user, the locale and chrony.
pgBackRest stays when a backup repository on the server has files. The log of
the operation names what the cleanup removed.
Needs cleanup
The server shows Needs cleanup, with the reason, when:
- the server was unreachable during the operation;
- the cleanup could not remove a part, for example a package;
- a deploy stopped because the server has PostgreSQL, TimescaleDB or
extension packages that the service did not install. The preflight
pg_packagesrow warns about this before the deploy.
When the server has no role and is online, the console retries the cleanup itself: after 1 minute at first, then at most every 30 minutes.
To run the cleanup now (admin role):
- Make sure that the server is in the mesh.
- On the server page, select Retry cleanup. The dialog lists what the console removes.
- If the server belongs to a service, deploy the service again.
The console refuses Retry cleanup while the server is in use. One exception: a server whose slot rebuild stopped on the packages of an earlier role. After the cleanup, rebuild the slot again.
Grow storage on a server
You can usually grow storage while PostgreSQL runs, with no restart or failover. Grow three layers in this order: the disk, the partition or logical volume, then the filesystem.
Run these commands on the server. First, find the data directory and its
mount. The default data directory is /var/lib/postgresql/<version>/main.
sudo grep -n '^[[:space:]]*data_dir:' /etc/patroni/patroni.yml
sudo findmnt -no SOURCE,FSTYPE,TARGET --target '<data_dir>'
If you cannot find the data directory or its mount, contact support before
you change storage. The examples use /dev/sda1 mounted at /. Use the
device, layout and filesystem that findmnt shows.
Grow the disk
Make the virtual disk or the LUN larger, or add a physical disk. Then check the size:
sudo lsblkIf lsblk shows the old size on a SCSI disk (/dev/sdX), rescan it:
# Replace sda with the disk that you grew.
echo 1 | sudo tee /sys/class/block/sda/device/rescan
NVMe and virtio-blk disks show the new size without a rescan. If the
size does not change, you may have to reboot. Before you reboot an HA
server, read Resize in place.
A reboot of the server of a Standard service stops the service. Do not continue
until lsblk shows the new size.
Grow the partition or the logical volume
For a partition, such as /dev/sda1 or /dev/nvme0n1p1:
# growpart <disk> <partition number>: /dev/sda1 -> sda 1
sudo growpart /dev/sda 1
For a logical volume, such as /dev/mapper/vg0-data, first grow the
physical volume (sudo pvs lists them). If the physical volume is a
partition, grow that partition with growpart first. Then:
sudo pvresize /dev/sda1
# -r also grows the filesystem. Skip the next step.
sudo lvextend -r -l +100%FREE /dev/mapper/vg0-data
growpart is in the cloud-guest-utils package.
Grow the filesystem
Skip this step if you used lvextend -r. ext4 and XFS grow while they
are mounted:
# ext4, by device
sudo resize2fs /dev/sda1
# XFS, by mount point
sudo xfs_growfs /
Check the result, for example with sudo df -h /.
Do the same for each backup repository of the service. Run findmnt for
each repository path:
- A remote repository is on the backup server, by default
/var/lib/pgbackrest-remote. - A local repository is on the database server, by default
/var/lib/pgbackrest.
You cannot shrink storage. To get a smaller volume, restore onto a new service, or replace the server.
Delete a server
You need the admin role. In the server menu, select Delete server and
type DELETE to confirm. Delete removes the server from the mesh and from
the console. You cannot undo it.
The console refuses the delete while the server:
- fills a member slot. Release it first (see Replace a server);
- hosts a LiveSync session;
- left a member slot that is empty or waits for its rebuild. Fill the slot, let the rebuild complete, then delete the server;
- holds backup data. Force delete server deletes it anyway, with no cleanup. The console then cannot restore from that backup data. Use it only for a dead server.
When the console reaches the server, it stops the database services on it (or runs its cleanup, if it shows Needs cleanup), then deletes it. When the server is Unreachable, the console deletes its record now, and the data on its disk stays.